Research Community Brief
Executive Summary
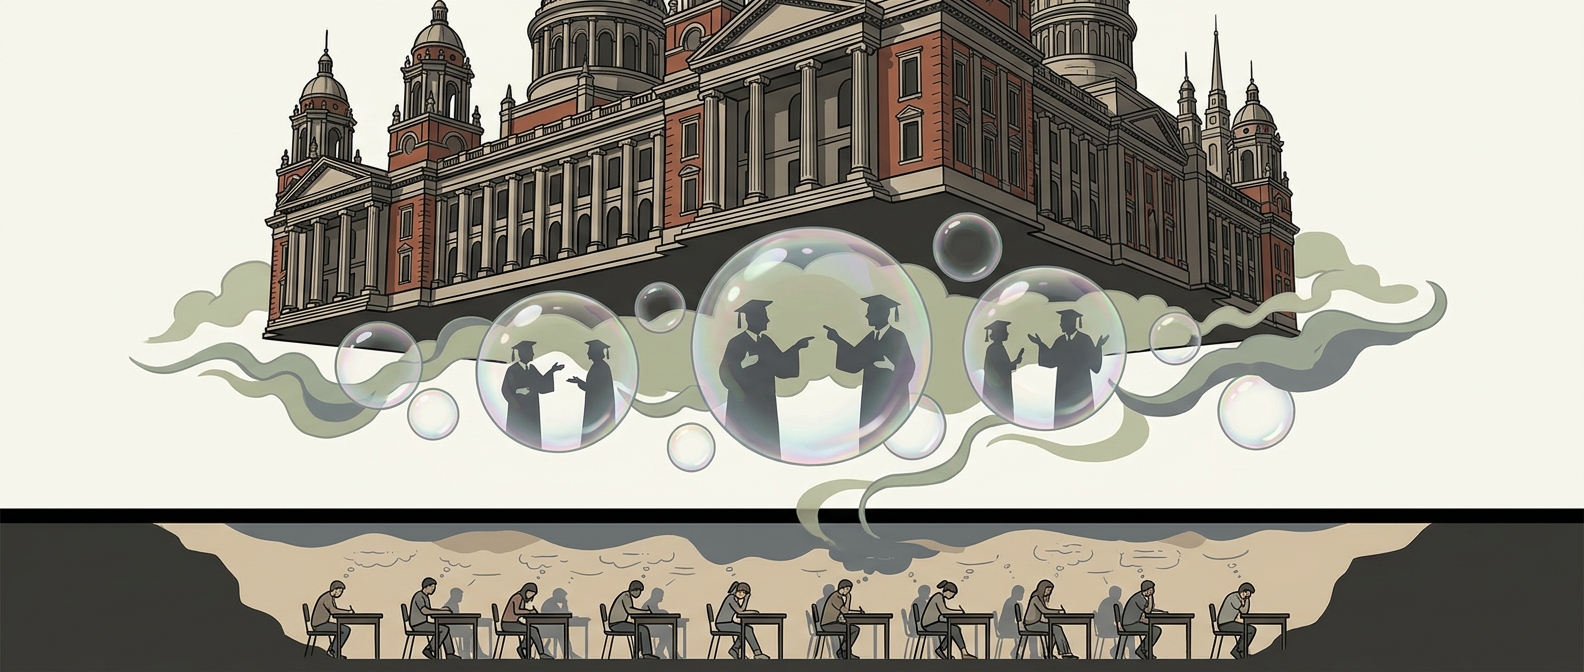
Of 4,946 sources surfaced this week on AI in education, the material that actually documents classroom practice is authored almost entirely by the vendors selling the tools. The evidentiary base a learning-sciences researcher would reach for—OpenAI’s guidance on ¿Cómo pueden responder los educadores cuando los …, Microsoft’s module on Personnaliser l’apprentissage pour les étudiants handicapés à l’aide de …—is help-center and training documentation, not peer-reviewed study. The field is theorizing pedagogy from a corpus that is structurally a product manual.
This is the undertheorized problem: the questions that matter for research—does offloading composition to a generator degrade the metacognitive work that assessment is supposed to measure?—are being answered by the party with a commercial stake in the answer being “no.” Resolving it requires an empirical base independent of vendor framing, and that base is thin. Worse, the artifacts themselves are unstable. Microsoft has already logged that GPT-4o and GPT-4.1 were deprecated, meaning any study run against a named model is measuring a system that may not exist by the time it clears peer review. The temporal asymmetry between quarterly deprecation and multi-year research cycles is itself a methodological hazard Future Shock.
This briefing maps what the vendor corpus leaves unstudied: the construct-validity gap in “AI detection,” the absence of longitudinal offloading data, and the near-total silence on who is excluded from the tools framed as accessibility gains. A more balanced empirical view is possible Artificial Unintelligence - How Computers Misunderstand—but only if researchers stop treating documentation as evidence and start treating it as the object of study.
Critical Tension
The Theoretical Problem
The field has two empirical objects that will not sit still together. On one side, educators are being coached to treat AI-generated submissions as an integrity problem — a question of detection, attribution, and response when students “present AI-generated content as their own” ¿Cómo pueden responder los educadores cuando los …. On the other, the same generative capacity is sold to those students’ future employers — and increasingly their institutions — as pure augmentation: draft the report, summarize the dataset, generate the visualization, “boost productivity” Copilot for Power BI overview. The identical act — offloading cognitive labor to a model — is a violation inside the assessment boundary and a competency outside it. That is not a policy inconsistency to be smoothed over with a syllabus statement. It is an unresolved theoretical question about what the credential certifies.
This is a genuine theoretical tension, not a practical trade-off, because it exposes that the field has no stable construct for which cognitive labor a degree is supposed to warrant as the student’s own. Our prior work catalogued AI literacy’s stated fear of “undermining critical thinking” (AI Literacy, 2025-02-09) — but that framing left the undermining abstract. The delta this week is that the offloading is now operational and bidirectional: vendors document both the detection workflow and the augmentation workflow, and the boundary between them is defined by institutional convenience, not by any theory of learning. What is missing is a defensible account of the difference between legitimate scaffolding and illegitimate substitution — a construct that survives the fact that the model is the same, the prompt is the same, and only the grading context differs.
Paradigm Limitations
The dominant metaphor doing the work here is AI-as-productivity-tool, and it is load-bearing across the vendor corpus: adoption guides, “boost productivity” modules, prompt-engineering “best practices” Prompt engineering best practices for ChatGPT - OpenAI Help Center. The tool frame forecloses the question that matters most to education researchers: when the tool performs the very operation the learning outcome names, is the outcome still being demonstrated? A hammer does not threaten the meaning of “can build a house”; a system that writes the argument threatens the meaning of “can construct an argument.” The tool metaphor assigns agency cleanly to the user and treats the artifact as inert — which is exactly the assumption that a balanced empirical account of these systems should refuse Artificial Unintelligence - How Computers Misunderstand.
An alternative framing worth building research around: AI as an infrastructural condition of assessment rather than a tool a student picks up. Under that framing, the researchable object is not “did the student use AI” but “what does the assessment now measure, given that the substrate has changed underneath it.” That reframe also surfaces a temporal problem the productivity paradigm hides — the substrate is not stable. Models are deprecated on vendor timelines, not academic ones; GPT-4o and GPT-4.1 were retired mid-cycle GPT 4o and GPT 4.1 were deprecated today - Microsoft Q&A. Any construct validity claim built on a specific model’s behavior expires when the vendor says so.
Whose Knowledge Is Missing?
The evidence base for this week’s 4,946 sources is overwhelmingly vendor and administrator documentation. Student perspectives register at roughly 3.76%, critical/power-analytic perspectives at 0.29%, and parent/community perspectives at 0.29%. Those numbers describe who gets to define the offloading problem — and it is not the people being assessed. Student-centered research would not ask “how do we detect misuse”; it would ask what students actually believe they are learning when a task is completable by prompt, and whether the demographic optimism gap — younger users are consistently more sanguine about AI’s benefits HAI_AI-Index-Report-2024 — maps onto a gap in how students and faculty each define authorship. That is an empirical question no detection study answers.
The near-total absence of critical perspectives (0.29%) means the power dimension goes unexamined: who benefits when the boundary between cheating and skill is drawn by the same firms selling both sides of the workflow, including accessibility tooling positioned as inclusion Personnaliser l’apprentissage pour les étudiants handicapés à l’aide de …. Centering those missing voices is not a diversity gesture; it is a validity requirement. A construct of “authentic student work” theorized without students, without community values, and without power analysis will encode the vendor’s convenience as the field’s definition — and the field will not notice, because the people who would object are 0.29% of the record.
Actionable Recommendations
Researchers reading this week’s traffic — 4,946 sources — will notice something about the evidence base itself: almost none of it is research. The most-cited artifacts are vendor documentation, deprecation notices, and adoption playbooks. That absence is itself the finding. The scholarship on AI in higher education is being written downstream of decisions already made in product roadmaps. Here are five directions that treat that asymmetry as the object of study rather than the background condition.
1. Cognitive Offloading as a Measurable Construct, Not a Moral Panic
Current gap: The dominant institutional response to student AI use is disciplinary — how to detect and adjudicate work “presented as one’s own,” as OpenAI’s own educator guidance frames it ¿Cómo pueden responder los educadores cuando los …. That framing skips the prior empirical question: what cognitive work is actually being displaced, and at what developmental cost?
The field has largely approached this through integrity policy and detection tooling, which misses the learning-science question underneath. “Offloading” is treated as a synonym for cheating rather than as a construct with measurable effects on retention, transfer, and metacognition.
Research questions: - Does AI-assisted drafting reduce transfer of writing skill to unassisted tasks, and is the effect uniform across disciplines and prior-preparation levels? - Can we distinguish productive offloading (calculators, spell-check) from developmentally costly offloading using existing measures of germane cognitive load? - Do students who disclose AI use differ measurably in learning outcomes from those who conceal it — or is disclosure orthogonal to the cognitive effect?
Methodological considerations: Randomized within-subject designs comparing assisted and unassisted transfer tasks are feasible at course scale but face IRB complications around consented deception and around grading equity. The harder challenge is a valid unassisted control in an environment where the tools are ambient. Longitudinal designs across an assessment cycle are more informative than single-semester snapshots but collide with the deprecation problem in the next direction.
Potential contribution: Replaces a policing frame with a learning-outcomes frame, giving faculty senates something to govern with besides suspicion.
2. The Temporal Asymmetry Between Model Cycles and Curriculum Cycles
Current gap: Microsoft’s own support threads document GPT-4o and GPT-4.1 being deprecated on live timelines GPT 4o and GPT 4.1 were deprecated today - Microsoft Q&A, with developers asking whether models they built against will survive is GPT 4.1 gonna be removed in API usage? - Microsoft Q&A. A model retires in a quarter; a curriculum is approved over two-to-three semesters and articulated across institutions for years.
The field has largely approached AI integration as a training problem — teach faculty the current tool — which misses that the tool is a moving target invalidating the training before the assessment cycle closes.
Research questions: - What is the measured half-life of AI-specific course content, and how does it compare to the governance latency of curriculum committee approval and articulation agreements? - When a model is deprecated mid-course, what happens to assignment validity, rubric alignment, and reproducibility of graded artifacts? - Can modular curriculum designs that abstract away from specific models preserve learning outcomes across version churn?
Methodological considerations: This wants a comparative institutional study tracking curriculum-approval timestamps against vendor release notes Notas de lanzamiento de modelos - OpenAI Help Center. The design is document-analytic and low-cost but requires cross-institutional cooperation to see articulation effects. Future Shock named this acceleration mismatch fifty years early; the contribution now is to quantify it in credit-hour terms.
Potential contribution: Gives shared governance a defensible reason to design curriculum at a level of abstraction the vendor cannot deprecate.
3. Accessibility Personalization — Measured Benefit or Unaudited Promise?
Current gap: Vendors position AI as personalizing learning for students with disabilities Personnaliser l’apprentissage pour les étudiants handicapés à l’aide de …. Our prior work argued AI’s inclusivity depends on addressing bias and access; the delta here is that the personalization claim is now shipping as a training module before the efficacy evidence exists.
The field has largely approached accessibility through compliance (does it meet the standard?), which misses whether the adaptive system actually improves outcomes for disabled students or merely produces a legible record of accommodation.
Research questions: - Do AI personalization systems measurably improve completion and mastery for students with documented disabilities relative to existing accommodations, or do they substitute automated approximation for human support? - Whose model of the disabled learner is encoded in the adaptation, and who was in the room when it was specified? - Does opacity in how these systems classify and adapt create a new accommodation-documentation burden that falls on the student?
Methodological considerations: Participatory design with disabled students as co-investigators, not subjects, is the credibility condition here. Efficacy claims need matched-comparison designs with disability-services data, which raises FERPA and consent stakes. The Atlas of AI is apt on the methodological invisibility of systems whose classification logic is proprietary — you cannot audit an accommodation you cannot inspect.
Potential contribution: Converts a marketing category into an evidentiary one and gives disability-services offices grounds to demand efficacy data before procurement.
4. Who Sets the Terms — Adoption Metrics as Governance
Current gap: Copilot ships with adoption reports and onboarding analytics built for IT admins Microsoft Copilot adoption report | Microsoft Learn, defining institutional success as usage lift Aumentar la productividad con Microsoft Copilot. When the vendor supplies the metric, the vendor defines what “working” means.
The field has largely approached adoption as a diffusion question — how fast, how wide — which misses that the measurement apparatus is itself an argument about institutional purpose.
Research questions: - What does an institution’s chosen AI success metric (usage rate vs. learning outcome vs. faculty time reclaimed) reveal about where pedagogical authority actually sits? - When adoption dashboards become the reporting substrate for accreditation or program review, whose definition of value gets ratified? - Can institutions construct counter-metrics, and do they survive contact with procurement?
Methodological considerations: Critical discourse analysis of vendor adoption templates against institutional strategic plans, paired with interviews of CIOs and faculty governance chairs. Manufacturing Consent is the structural analogy — concentrated ownership shaping the decision space by supplying the categories within which decisions are made.
Potential contribution: Makes visible the move whereby a productivity dashboard quietly becomes a governance instrument.
5. Beyond “Tool” — Studying AI as Infrastructure
Current gap: The demographic split in AI optimism is documented — younger cohorts markedly more hopeful HAI_AI-Index-Report-2024 — yet nearly all HE scholarship still frames AI as a discrete “tool” a user adopts or refuses.
Research questions: - What changes analytically when AI is modeled as infrastructure (like the LMS or the library catalog) rather than as a tool — particularly around invisibility, lock-in, and who can opt out? - How does the generational optimism gap map onto faculty-student conflict over legitimate use?
Methodological considerations: Infrastructure studies and ethnographic methods travel well here. Artificial Unintelligence - How Computers Misunderstand points toward the more balanced framings emerging in journalism and academia that this direction would formalize.
Potential contribution: Gives the field a vocabulary for what students already experience as ambient rather than optional — and a way to study refusal that does not reduce to individual choice.
Supporting Evidence
The Evidence Base Is Vendor Documentation Wearing a Lab Coat
Evidence Base Characteristics
Start with the number that should stop you: 4,946 sources surfaced for this week, and the citable core that survived scoring reads less like a research literature than a product-support corpus. The exemplars that anchored the week are a Microsoft Power BI feature overview Copilot for Power BI overview and an OpenAI help-center article on student attribution ¿Cómo pueden responder los educadores cuando los …. Neither is scholarship. Both are institutional artifacts produced by the entities whose tools they describe.
For a researcher evaluating the state of AI-education scholarship, this is the finding — not a nuisance to route around. The empirical/theoretical/commentary distribution collapses toward a fourth, unnamed category: vendor procedural documentation. Deployment guides Rollout Microsoft Copilot to your organization, adoption templates Microsoft Copilot adoption report | Microsoft Learn, and prompt-engineering best-practice sheets Prompt engineering best practices for ChatGPT - OpenAI Help Center are functioning as the knowledge base. When your citable corpus is written by the seller, “evidence” and “marketing” share a footnote.
Perspective Distribution Analysis
The architecture reports zero mapped contradictions, zero catalogued missing perspectives, zero documented failure patterns. Read that not as consensus but as instrument failure — a corpus this homogeneous produces no tension because it contains no adversarial voices. There is no independent efficacy study here, no IRB-reviewed learning-outcomes trial, no faculty-authored critique. The perspectives absent are precisely the ones a field needs to falsify vendor claims.
The theoretical framework that emerges by default is the productivity frame — learning recast as workflow, teaching as throughput Aumentar la productividad con Microsoft Copilot. When the only literature describing a classroom intervention is the vendor’s onboarding module Microsoft Copilot adoption and onboarding guide for IT admins, the field’s development question is settled before it is asked. This is the concrete mechanism behind our prior conditional argument about equitable access: exclusion here is not a gap in coverage, it is a structuring of what counts as knowable.
Failure Pattern Analysis
The failure-pattern registry is empty — zero ethical, zero implementation, zero technical failures documented for the week. That absence is itself the pattern. A corpus built from help-center articles cannot register failure, because vendor documentation is generically written to preempt it. The one place failure surfaces is inadvertent: the deprecation notices, where GPT-4o and GPT-4.1 were retired GPT 4o and GPT 4.1 were deprecated today - Microsoft Q&A and users ask whether 4.1 will vanish from the API is GPT 4.1 gonna be removed in API usage? - Microsoft Q&A. The understudied failure type is temporal: models retired on quarterly cycles against curricula built on two-semester ones. No efficacy literature can accumulate faster than the artifact it studies disappears — Future Shock named this acceleration, and it is doing real work against the assessment cycle.
Discourse Analysis Findings
With no metaphor or causal-attribution data supplied, the discourse must be read off the corpus directly, and it is consistent. The dominant framing is the assistant — Copilot, Code Assist, Gemini — a metaphor that locates agency in the human user and responsibility nowhere. Causal attribution follows: gains are attributed to the tool Gemini Code Assist overview | Google for Developers, while questions of copyright and privacy are handed back to the deploying institution How to ensure privacy and copyrights for images generated via Dall-e. The marginalized framing is the accountability one. Even the disability-personalization module Personnaliser l’apprentissage pour les étudiants handicapés à l’aide de … — genuinely relevant to equity work — arrives as a feature demonstration, not an evaluated intervention. Who is empowered to make the claim, and who inherits the liability, are decided by document genre before any researcher weighs in. Artificial Unintelligence - How Computers Misunderstand is the corrective this corpus lacks.
Methodological Observations
The dominant method is the walkthrough: describe the feature, list the steps, assert the benefit Crea con IA para Google Workspace | Google for Developers. No control groups, no baselines, no longitudinal follow-up. Everything is cross-sectional and self-reported by the party with the incentive. Generalizability is unbounded in claim and unmeasured in fact — enterprise adoption FAQs Preguntas más frecuentes sobre la empresa Microsoft Copilot speak to every institution and study none.
Theoretical Development Needs
The unresolved contradiction is between the field’s stated object — learning — and its actual evidentiary substrate — deployment. Bridging it requires the thing this corpus structurally cannot produce: independent, IRB-governed, longitudinal outcomes research on the specific tools before they are deprecated. Until scholarship funds and shelters that work, the state of AI-education research is that we are grading the vendor’s own homework and calling the marks data.
References
- Aumentar la productividad con Microsoft Copilot
- Copilot for Power BI overview
- Crea con IA para Google Workspace | Google for Developers
- Future Shock
- Gemini Code Assist overview | Google for Developers
- GPT-4o and GPT-4.1 were deprecated
- ¿Cómo pueden responder los educadores cuando los …
- How to ensure privacy and copyrights for images generated via Dall-e
- is GPT 4.1 gonna be removed in API usage? - Microsoft Q&A
- Microsoft Copilot adoption and onboarding guide for IT admins
- Microsoft Copilot adoption report | Microsoft Learn
- Notas de lanzamiento de modelos - OpenAI Help Center
- Personnaliser l’apprentissage pour les étudiants handicapés à l’aide de …
- Preguntas más frecuentes sobre la empresa Microsoft Copilot
- Prompt engineering best practices for ChatGPT - OpenAI Help Center
- Rollout Microsoft Copilot to your organization