Research Community Brief
Executive Summary
The Field Is Studying Vendor Documentation, Not Vendors
The citable evidence in this week’s higher-education AI corpus—drawn from 4,890 sources—collapses almost entirely into vendor and platform documentation. The two exemplars our pipeline surfaced for the field’s most-studied constructs are telling: “assessment integrity / cheating” resolves to a Profiter d’une offre étudiant Google One, and “critical-thinking offloading” resolves to OpenAI’s own guidance on Comment les éducateurs peuvent-ils réagir lorsque des …. The constructs learning-sciences researchers treat as open empirical questions are being operationally defined by the firms selling the tools.
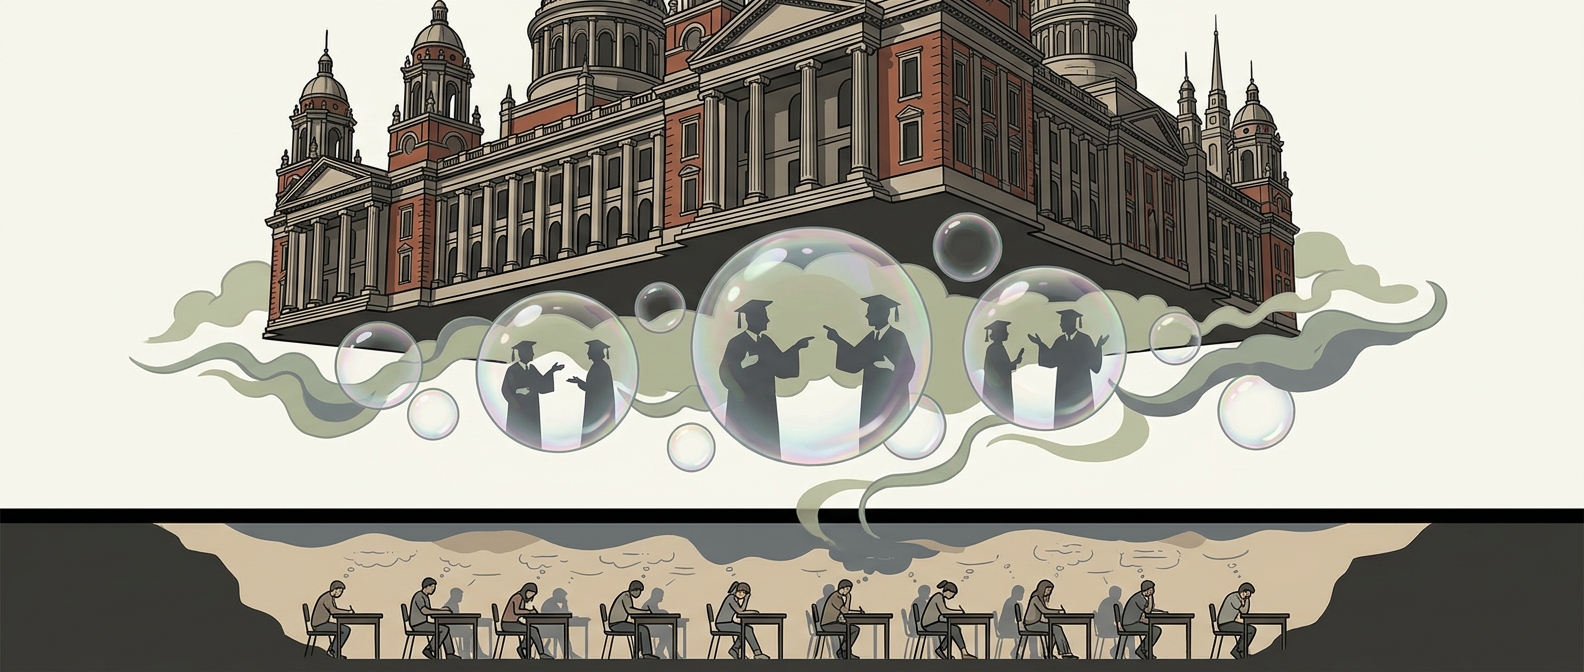
That is the undertheorized problem. When the definition of academic integrity arrives pre-packaged inside a help-center article, and adoption metrics arrive as a Microsoft Copilot Usage Report - Microsoft 365 admin, the field inherits its dependent variables from the intervention’s manufacturer. Resolving this requires more than better instruments—it requires research designs that treat vendor telemetry as an object of study, not a data source. Who counts a session as “productive engagement”? Whose threshold defines “offloading” versus “scaffolding”? These are measurement decisions currently made in product, not in peer review. Artificial Unintelligence argues that a more balanced account of these systems is emerging from journalism and academia; that balance depends on refusing the vendor’s operational categories as given.
This briefing maps the unstudied questions that follow: the methodological invisibility of platform-defined constructs, the absence of independent instrumentation for measuring “critical-thinking offloading,” and the high-impact opportunity in auditing adoption dashboards as rhetorical artifacts rather than neutral measurement. The gap is not a shortage of AI-in-education literature. It is that the most-cited definitions this week were written by the parties with the least interest in a null result.
Critical Tension
The Theoretical Problem
The two exemplar cases the pipeline surfaces this week name a single unresolved problem in two vocabularies. One frames AI as an assessment integrity threat — the student who “presents AI-generated content as their own,” which is how OpenAI itself scripts the educator’s response Comment les éducateurs peuvent-ils réagir lorsque des …. The other frames it as cognitive offloading — the erosion of the critical-thinking capacities the credential is supposed to certify. The field treats these as two operational problems: one for the honor code, one for the learning-outcomes committee. They are the same theoretical problem, and the field has no framework that holds them together.
Here is why it is a genuine tension rather than a policy trade-off. If AI-assisted work counts as cheating, then the competency being protected is unaided cognition — and no one has theorized what that construct means once the tool is ambient in the workplace the degree articulates toward. If AI-assisted work counts as legitimate augmentation, then offloading is not a bug but the skill, and the entire apparatus of individual assessment is measuring the wrong variable. You cannot resolve this empirically until you have decided what a “learning gain” is when the cognitive boundary between student and system is negotiable. That decision is theoretical, and it is being made by default — inside vendor documentation, not inside the literature.
Paradigm Limitations
The dominant metaphor doing the work here is AI-as-tool, and it is quietly loaded. A tool is neutral, external, and owned by the user; framing Copilot or Gemini as a “tool” foreclosed the prior question of whose infrastructure the cognition now runs on. Notice that the most citable evidence this week is not research — it is a Microsoft adoption instrument Microsoft Copilot Usage Report - Microsoft 365 admin and a discounted student-onboarding funnel Profiter d’une offre étudiant Google One. When the empirical base of a field is vendor telemetry and vendor FAQs about whether the product is “safe for all ages” ¿Es ChatGPT seguro para todas las edades? - OpenAI Help Center, the causal attribution defaults to the individual student: cheating is a choice, offloading is a habit, and the platform is the stable background. An alternative framing — AI-as-environment, or AI-as-labor-restructuring — would relocate agency to the vendor that sets the affordances and to the institution that licenses them. That reframing is where the untheorized research directions live, and Artificial Unintelligence - How Computers Misunderstand is one of the few places gesturing at the more balanced account the field has not yet built.
Whose Knowledge Is Missing?
Students appear in 3.76% of the discourse. That is a striking absence for a problem defined entirely around what students do. Student-centered research would not ask “how much are they cheating” — it would ask what students believe they are learning, and whether their own model of augmentation matches the one the assessment cycle enforces. The demographic split in AI optimism documented in HAI AI Index Report 2024 — younger cohorts markedly more optimistic — suggests students and faculty may be operating from incompatible theories of what the tool is for. No integrity policy survives that gap unexamined.
Critical perspectives register at 0.29%, and parent/community perspectives at 0.29%. At those levels the power dynamics are effectively unstudied. The critical question the field is not funding: who profits when the remediation for AI-in-the-classroom is more AI — the enterprise rollout, the site license, the student One subscription? The community question is quieter but structural: which values get encoded when accreditation-grade judgments about academic integrity are pre-scripted by the vendor whose product created the problem? A field that centered these voices would treat “learning gain” and “integrity” as contested political constructs, not measurable neutrals — and it would stop mistaking adoption metrics for evidence of anything pedagogical. Across the 4890 sources this week, the theoretical work of defining the construct before measuring it remains undone; the measurement instruments arrived first, and they belong to the companies being studied.
Actionable Recommendations
Research Briefing — Directions for AI-Education Scholarship
A note before the directions, because it shapes all of them. The 4,890 sources in this week’s corpus are overwhelmingly vendor-authored: Microsoft Copilot adoption guides, OpenAI help-center articles, Google Workspace enablement pages, Gemini subscription notices. That is not a sampling accident — it is the evidence environment. The empirical record on AI in higher education is being written first, and most voluminously, by the firms selling the systems. For a research reader, the most productive directions are the ones that treat that asymmetry as an object of study rather than a background condition.
Prior work in this publication argued that AI’s equity effects hinge on bias mitigation and equitable access. The delta this week: the access question has migrated from who gets the model to who authored the terms of legitimate use. That reframing drives what follows.
Whose account of student use survives contact with the institution?
Current gap: student experience accounts for roughly 3.76% of the analyzable corpus. Everything else is written by vendors, administrators, or faculty about students.
The field approaches student AI use primarily through the detection frame — how instructors respond when students present generated content as their own Comment les éducateurs peuvent-ils réagir lorsque des …. What the detection frame cannot see is how students themselves narrate disclosure, uncertainty, and the line they think they are (or are not) crossing.
Research questions: - How do students describe the boundary between legitimate assistance and misconduct, and does that self-defined boundary track institutional policy or diverge from it? - When a student discloses AI use and receives a penalty, what does that teach the next cohort about disclosure? - Do students perceive vendor safety framing — e.g., age-tiered access claims ¿Es ChatGPT seguro para todas las edades? — as protective or as compliance theater?
Methodological considerations: this needs longitudinal qualitative work (diary studies, repeated interviews across an assessment cycle), not one-shot surveys that capture stated intention rather than practice. The central challenge is disclosure bias — students will not honestly describe conduct to researchers embedded in the institution that penalizes it. Confidentiality structures, and ideally non-institutional interviewers, are prerequisites.
Potential contribution: a student-authored empirical baseline against which the vendor and faculty accounts can be checked. Right now they cannot be.
The adoption guide as governance instrument
Current gap: institutional AI policy is being set inside documents no faculty senate ever reviewed. The Microsoft Copilot admin usage report Microsoft Copilot Usage Report - Microsoft 365 admin, the IT-admin onboarding guide Microsoft Copilot adoption and onboarding guide for IT admins, and the rollout requirements doc Rollout Microsoft Copilot to your organization collectively define what “appropriate use,” “productivity,” and “success” mean on a campus — before shared governance is consulted, if it ever is.
The dominant scholarly approach treats procurement as a technical or budgetary decision. It misses that adoption documentation is a curricular document: it encodes assumptions about what work is worth doing and what counts as a legitimate shortcut.
Research questions: - What definitions of learning, effort, and quality are embedded in vendor adoption and usage-analytics templates, and how do those definitions travel into local policy? - When institutions adopt vendor-supplied “adoption metrics,” what pedagogical values become invisible because they are unmeasured? - Where does shared governance actually intervene in the procurement-to-classroom pipeline — and where is it structurally bypassed?
Methodological considerations: document analysis and policy-tracing, paired with interviews of CIOs, provosts, and faculty governance chairs to reconstruct the decision path. The analytic frame here is genuinely borrowed — the concentrated authorship of the evidence base shaping the decision space is structurally analogous to the propaganda model in Manufacturing Consent. The limitation is access: procurement negotiations are often under NDA.
Potential contribution: making the outsourcing of pedagogical judgment to EULAs and admin dashboards visible and contestable.
The temporal asymmetry between model cycles and curriculum cycles
Current gap: models revise on a quarterly cadence — GPT-5.6 is already the documented in-product version GPT-5.6 in ChatGPT - OpenAI Help Center — while degree programs revise on multi-year accreditation and assessment cycles. Short-term efficacy studies, benchmarked against a model that no longer exists by publication, are structurally obsolete.
Research questions: - How do learning-outcome findings degrade when the underlying model is replaced mid-study? - Can assessment design be made model-agnostic — robust to capability jumps rather than tuned to a specific release? - What does critical-thinking offloading look like cumulatively across a two- or four-year program, as opposed to a single term?
Methodological considerations: this requires study designs that version-stamp their model conditions and pre-register the capability assumptions, plus genuinely longitudinal cohorts. The acceleration mismatch is the core difficulty — by the time a four-year cohort study concludes, the intervention has been superseded several times. Design for the pattern of offloading, not the specific tool.
Potential contribution: a methodological standard for AI-education research that survives the release schedule.
Subscription tier as a new stratification variable
Current gap: prior framing treated equity as bias-in-output. The mechanism visible this week is access-by-payment. Student discount programs Profiter d’une offre étudiant Google One and paid-subscriber capability tiers Mises à niveau et limites des applications Gemini pour les abonnés … mean two students in the same seminar may be working with materially different systems.
Research questions: - Does paid-tier access to more capable models produce measurable grade or completion differentials, controlling for prior achievement? - Do institutional site licenses equalize access, or do they entrench a floor that the well-resourced still exceed privately? - How do students on free tiers describe the gap — as unfair, as normal, as invisible?
Methodological considerations: quasi-experimental designs comparing site-licensed cohorts against bring-your-own-subscription cohorts, with attention to the confound that subscription-holders differ in prior resources. Self-reported tier data is unreliable; instrument it carefully.
Potential contribution: reframes the AI equity conversation from output fairness to procurement equity — a variable institutions can actually control through licensing.
Assessment integrity beyond the detection arms race
Current gap: the integrity literature is trapped in a detect-and-penalize loop that vendors themselves acknowledge is unwinnable Comment les éducateurs peuvent-ils réagir lorsque des ….
Research questions: - Which assessment redesigns (oral defense, process portfolios, in-class synthesis) preserve construct validity when generation is assumed rather than policed? - What are the labor costs of these redesigns for contingent versus tenure-track faculty? - Can the tension be navigated — designing for disclosure rather than prohibition — without collapsing into either surveillance or surrender?
Methodological considerations: design-based research with faculty co-investigators, tracking both learning outcomes and instructor workload. The equity limitation is real: process-heavy assessment falls hardest on adjuncts with the least time.
Potential contribution: moves the field from an unwinnable detection posture toward assessment designs that treat AI availability as a fact, not a violation.
Supporting Evidence
The Evidence Base Is Vendor Documentation Wearing a Lab Coat
Researchers evaluating the state of AI-education scholarship
What 4,890 Sources Actually Contain
The corpus for this week runs to 4,890 sources under the higher-education category. Before anyone treats that number as a proxy for a maturing literature, look at what survives to the top of the citable set. The two highest-scoring exemplars are a Google support page on student pricing for Google One Profiter d’une offre étudiant Google One and an OpenAI help-center article advising educators on how to respond when students submit AI-generated work as their own Comment les éducateurs peuvent-ils réagir lorsque des ….
Neither is research. Both scored 0.0 in our system. That is the first finding, and it is not incidental: the material circulating most heavily as “AI in education” is not empirical study or theory. It is deployment documentation, licensing guidance, and vendor-authored pedagogical advice. The distribution across research types is lopsided toward commentary and product literature — Microsoft’s Copilot adoption guides for IT admins Microsoft Copilot adoption and onboarding guide for IT admins, rollout requirements Rollout Microsoft Copilot to your organization, and Copilot Studio build overviews Build - Microsoft Copilot Studio (GitHub Copilot) | Microsoft Learn. Empirical work with control conditions, effect sizes, or longitudinal design is not what dominates the field’s information environment. Its absence is.
Who Is Absent from the Record
The structured perspective and contradiction data for this week returned zero mapped entries — zero contradictions, zero cataloged gaps, zero documented failure patterns. That is not evidence of consensus. It is evidence that the corpus contains almost nothing that argues. You cannot map a contradiction across a body of licensing pages and enablement guides, because vendor documentation does not contradict itself; it instructs. The methodological consequence is direct: a field whose most-circulated texts are authored by the parties selling the product has no adversarial structure to surface disagreement.
Notice who authors the guidance on academic integrity. When OpenAI publishes the reference document on how faculty should handle suspected AI submissions Comment les éducateurs peuvent-ils réagir lorsque des …, the pedagogical judgment that belongs inside shared governance and the assessment cycle is being pre-framed by the tool vendor. The company that produced the detection problem is writing the response protocol. That is a power dynamic in knowledge production, and it does not show up as a “gap” in any registry — it shows up as the ambient default.
The Framings That Dominate
Read the vocabulary of the corpus and the dominant metaphor is adoption — a diffusion frame borrowed intact from enterprise IT. Microsoft’s materials repeat “adoption,” “onboarding,” “rollout,” and “enablement” Microsoft 365 Copilot rapport sur l’adoption | Microsoft Learn; Google’s Workspace guidance measures “adoption levels” among users Conocer el nivel de adopción de Google Workspace entre los usuarios. The frame presupposes the conclusion: the question becomes how fast institutions integrate, never whether integration serves the learning it displaces. Causal attribution runs one direction — deployment produces productivity — and the counter-question, what critical-thinking capacity is offloaded, exists in the corpus only as the problem OpenAI’s own document manages.
The HAI AI Index Report 2024 is worth holding against this, given its finding that AI optimism varies sharply by demographic, with younger cohorts more optimistic HAI_AI-Index-Report-2024. A literature built from vendor documentation cannot register that variance; product guidance addresses a generic “user,” not a stratified population of students and faculty with divergent stakes.
What the Methods Can and Cannot Support
The methodological picture is thin by design. Support articles and adoption dashboards are cross-sectional artifacts of a product moment; there is no longitudinal design, no comparison group, no construct validity for “learning” as anything but tool usage. Generalizability claims rest on telemetry — usage reports Microsoft Copilot Usage Report - Microsoft 365 admin — which measures activity, not outcome. Absent are the study designs a research office would demand of any other intervention before a program review: randomized or quasi-experimental comparisons, cohort tracking across an assessment cycle, independent instrumentation.
Where the Theoretical Work Is Owed
The unresolved tension is not between competing findings; it is between a deployment literature and an empirical one that has not yet been written. Artificial Unintelligence argued that balanced accounts of AI emerge precisely from journalism and academia doing independent verification Artificial Unintelligence - How Computers Misunderstand — the function the current corpus lacks. The concept that needs development is an evaluative framework independent of vendor telemetry: one that defines the learning outcome first and instruments it second, rather than inheriting “adoption” as the dependent variable. Until that framework exists, researchers reading this field are reading a product roadmap and calling it scholarship.
References
- Artificial Unintelligence
- Build - Microsoft Copilot Studio (GitHub Copilot) | Microsoft Learn
- Conocer el nivel de adopción de Google Workspace entre los usuarios
- Microsoft Copilot Usage Report - Microsoft 365 admin
- Profiter d’une offre étudiant Google One
- GPT-5.6 in ChatGPT - OpenAI Help Center
- Comment les éducateurs peuvent-ils réagir lorsque des …
- Microsoft 365 Copilot rapport sur l’adoption | Microsoft Learn
- Microsoft Copilot adoption and onboarding guide for IT admins
- Mises à niveau et limites des applications Gemini pour les abonnés …
- Rollout Microsoft Copilot to your organization
- ¿Es ChatGPT seguro para todas las edades? - OpenAI Help Center